Book a Free Strategy Call
Skip the read: talk to Walid in 30 min.
Free strategy call. We map your AI engineering team, you keep the notes.
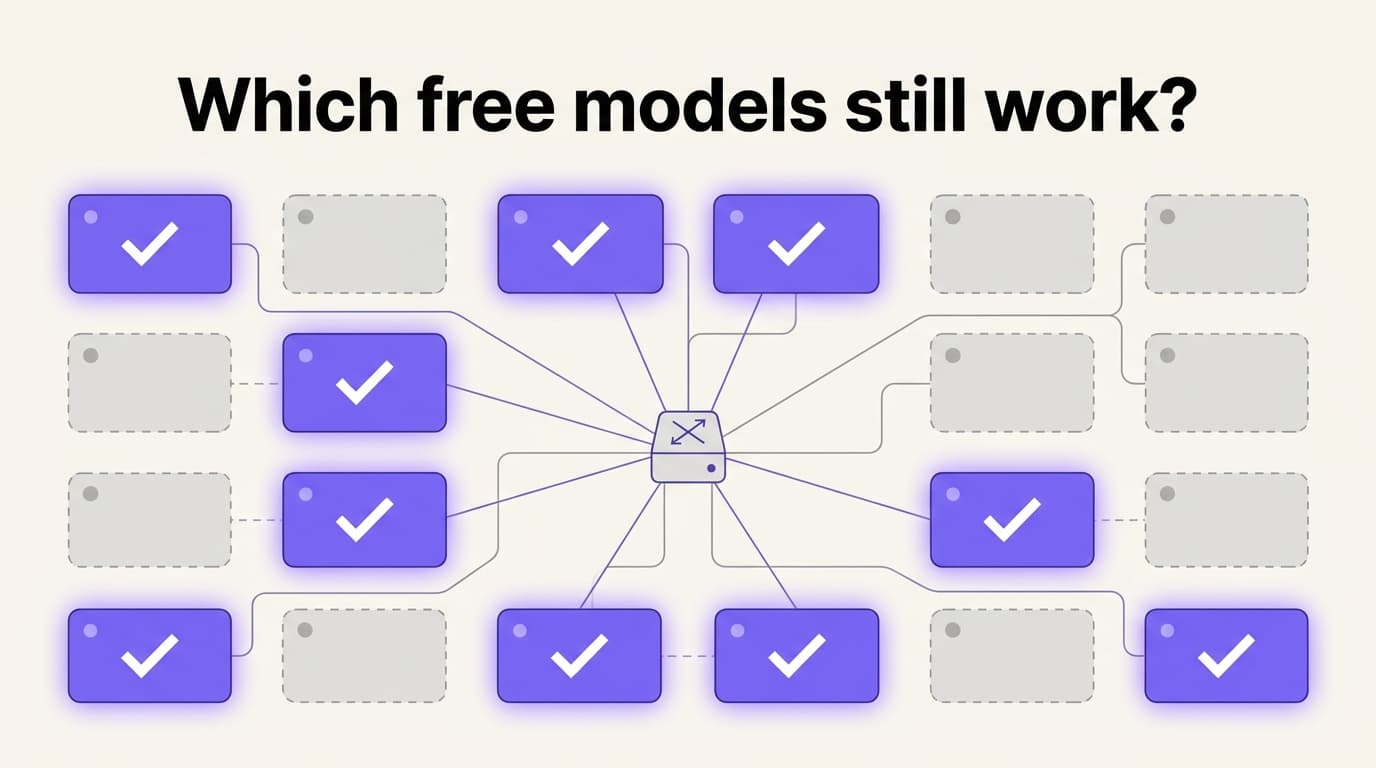
On November 3, 2026, OpenRouter lists 14 :free model IDs, and only 6 of them answered all three of our test calls. Three returned HTTP 429 every time. Two failed with a provider error every time, two only work inside approved agent apps, and one answered once. Free IDs that older guides still recommend, such as openai/gpt-oss-120b:free, qwen/qwen3-coder:free and meta-llama/llama-3.3-70b-instruct:free, now return a 404.
If your :free model started failing this week, this is probably why. The free catalog turns over every few weeks, and blog posts don't update when it does. On November 3 we pulled OpenRouter's models API and per-model endpoints API, sent a tiny request to every free model, and checked 27 older free IDs that tutorials still point to. We had run the same script on October 29, and in those five days the list changed: two models left, two went from working to failing every call, one more stopped answering, and two recovered.
You get the full table of what works today, what changed since October 29, what each dead ID now costs on its paid slug, the real request limits, and the script so you can re-run the check yourself.
Which OpenRouter free models work right now?
Six :free models answered all three passes on November 3, 2026: NVIDIA Nemotron 3.5 Super VL, Dots3-Note Preview, NVIDIA Nemotron 3.5 Lightning, Cohere North Mini Code, NVIDIA Nemotron 3 Ultra and NVIDIA Nemotron 3 Nano Omni Reasoning. Each model got the same request three times in separate sweeps, a minute or more apart: "Reply with the word OK and nothing else." with max_tokens set to 32.
"Answered" means HTTP 200 with text or reasoning output. It tests whether the endpoint serves you. It doesn't measure answer quality.
| Model ID | Context | Provider | Answered (of 3) | Notes |
|---|---|---|---|---|
nvidia/nemotron-3.5-super-vl:free | 1,000,000 | Nvidia | 3 | Text, image and video input; 0.7 to 0.9 s |
dots-studio/dots-3-note-preview:free | 512,000 | AtlasCloud | 3 | Slowest: 2.6 to 10.2 s. Catalog expiration date: 2026-12-31 |
nvidia/nemotron-3.5-lightning:free | 1,000,000 | Nvidia | 3 | Answered 2 of 3 on Oct 29 |
cohere/north-mini-code:free | 256,000 | Cohere | 3 | Agentic coding model |
nvidia/nemotron-3-ultra-550b-a55b:free | 1,000,000 | Nvidia | 3 | 94% uptime over the last day |
nvidia/nemotron-3-nano-omni-30b-a3b-reasoning:free | 256,000 | Nvidia | 3 | Answered 1 of 3 on Oct 29 |
liquid/lfm-2.5-2.6b:free | 65,536 | Liquid | 1 | Then 429 twice |
xingchen-agi/xing4.0-29b-a4b:free | 262,144 | Phala | 0 | 429 every time (2 of 3 answered on Oct 29) |
google/gemma-4-31b-it:free | 262,144 | Google AI Studio | 0 | 429 every time |
google/gemma-4-26b-a4b-it:free | 262,144 | Google AI Studio | 0 | 429 every time |
recursive/flint-v1.0:free | 262,144 | Recursive | 0 | 503 every time; 0% uptime over the last day (3 of 3 on Oct 29) |
nvidia/nemotron-3.5-content-safety:free | 128,000 | Nvidia | 0 | 404 "Provider returned error"; 0% uptime (3 of 3 on Oct 29) |
thinkingmachines/inkling:free | 1,048,576 | Thinking Machines | 0 | 403: agentic apps only. Expires 2026-11-04 |
thinkingmachines/inkling-small:free | 1,048,576 | Thinking Machines | 0 | 403: agentic apps only. Expires 2026-11-04 |
Every free model is served by a single provider. If that one provider is busy, there is no second endpoint to fall back to.
The catalog also lists three zero-priced IDs without the :free suffix: the openrouter/free router (below) and two Google Lyria 3 music previews. The Lyria previews take a prompt and return audio, so our text probe doesn't apply to them, and we left them out of the counts.
What we found: the endpoints API showed 100% uptime over the last day for both Gemma 4 free endpoints, and all six of our Gemma requests still got a 429, the same result as on October 29. Uptime describes the provider. It says nothing about whether the shared free pool has room for your request.
What changed between October 29 and November 3?
We ran the same script on both days. In five days:
- Two models left the catalog.
poolside/laguna-s-2.1:freeandpoolside/laguna-xs-2.1:freecarried an expiration date of 2026-10-31 on October 29, and both were gone by November 3. That took the list from 16:freeIDs to 14. - Two working models broke. Recursive Flint and Nemotron 3.5 Content Safety answered all three calls on October 29. On November 3 their endpoints showed 0% uptime, and every call failed with a 503 or a 404 provider error. Both are still listed in the catalog.
- Two flaky models recovered: Nemotron 3.5 Lightning went from 2 of 3 to 3 of 3, and Nemotron 3 Nano Omni Reasoning from 1 of 3 to 3 of 3.
- Xing 4.0 got worse. It went from 2 of 3 to 0 of 3, with a 429 every time.
- A paid model disappeared too.
nousresearch/hermes-3-llama-3.1-405b:freepointed to a paid ID on October 29. By November 3 the paid ID had no provider either. - Two more are about to go. Both Thinking Machines Inkling models now show an expiration date of 2026-11-04.
So the count of working models stayed at six, but two of the six are different. A list of OpenRouter free models goes stale within days, not months.
Why do gpt-oss-120b:free, qwen3-coder:free and other free models return 404?
They are no longer free. Of the 27 older free IDs we checked, none appear in OpenRouter's catalog, none have a free endpoint, and every request failed. The error tells you which kind of dead you hit:
- 15 IDs return 404 with "This model is unavailable for free. The paid version is available now - use this slug instead: ..." followed by the paid ID. The model still runs, at a price.
- 11 IDs return 404 with "...is no longer available on OpenRouter: no provider serves this model anymore." Nobody serves the model, free or paid.
- 1 ID,
nvidia/nemotron-nano-30b-a3b:free, returns 400: "not a valid model ID".
Here is what the 15 still-running models cost if you drop the :free suffix. The price is from the endpoint with the lowest input price on November 3.
| Old free ID | Paid ID endpoints | Lowest input / output, $ per 1M tokens |
|---|---|---|
openai/gpt-oss-120b:free | 27 | $0.03 / $0.15 |
openai/gpt-oss-20b:free | 11 | $0.01 / $0.043 |
qwen/qwen3-coder:free | 2 | $0.30 / $1.00 |
qwen/qwen3-next-80b-a3b-instruct:free | 4 | $0.072 / $0.88 |
meta-llama/llama-3.3-70b-instruct:free | 10 | $0.10 / $0.32 |
meta-llama/llama-3.2-3b-instruct:free | 2 | $0.05 / $0.33 |
meta-llama/llama-4-maverick:free | 3 | $0.1875 / $0.6525 |
nvidia/nemotron-3-super-120b-a12b:free | 3 | $0.08 / $0.45 |
deepseek/deepseek-chat-v3-0324:free | 2 | $0.25 / $1.00 |
google/gemma-3-27b-it:free | 5 | $0.08 / $0.16 |
z-ai/glm-4.5-air:free | 3 | $0.13 / $0.85 |
moonshotai/kimi-k2:free | 1 | $0.57 / $2.30 |
moonshotai/kimi-k2.6:free | 17 | $0.39 / $1.80 |
cognitivecomputations/dolphin-mistral-24b-venice-edition:free | 1 | $0.20 / $0.90 |
tencent/hy3:free | 5 | $0.132 / $0.528 |
The 11 IDs with no provider left: nousresearch/hermes-3-llama-3.1-405b:free, poolside/laguna-m.1:free, poolside/laguna-xs.2:free, deepseek/deepseek-r1:free, mistralai/mistral-7b-instruct:free, arcee-ai/trinity-large-thinking:free, nvidia/nemotron-nano-12b-v2-vl:free, nvidia/nemotron-nano-9b-v2:free, liquid/lfm-2.5-1.2b-instruct:free, liquid/lfm-2.5-1.2b-thinking:free and openrouter/owl-alpha. None of these 11 paid IDs had an endpoint either. Hermes 3 405B still had one on October 29.
The cheap end matters here. At $0.03 per million input tokens, a million input tokens on the paid openai/gpt-oss-120b costs three cents. For a prototype, that is usually cheaper than the time you'd spend chasing the next free ID.
Free weekly brief
Steal our production automations
The exact n8n flows, Claude Code setups, and prompts we ship for clients, broken down step by step. No spam, unsubscribe anytime.
What are the OpenRouter free model limits in 2026?
Free models are capped at 20 requests per minute, and the daily cap depends on how many credits you have ever bought. OpenRouter's limits page gives two tiers:
| All-time credits purchased | Requests per minute | Requests per day |
|---|---|---|
| Less than 10 | 20 | 50 |
| 10 or more | 20 | 1,000 |
The tier follows "all-time credits purchased", so buying 10 credits once is enough to move you to 1,000 a day. The page adds that the higher cap actually starts one credit below the threshold, to absorb rounding and top-up fees. It also warns that a negative credit balance can cause errors on free models too. Paid variants have "no platform-level request cap".
Some older guides quote 200 requests per day, and so did several rows in our own free models directory until this check. OpenRouter's current page doesn't list that figure.
You can see your own counter. GET https://openrouter.ai/api/v1/key with your key returns a free_model_daily_requests object with used, limit and remaining fields, counted per UTC day. On November 3 our run sent 78 requests, 22 of them came back with an answer, and afterwards the counter read 22 used of 1,000. As far as we could tell, rejected requests (404, 403, 429, 503) did not count. OpenRouter's limits page doesn't say either way.
Is the openrouter/free router a safe default?
Not for anything you need to be predictable. openrouter/free is a router that, in its own catalog description, "selects free models at random from the models available on OpenRouter". It answered all three of our calls on both days, but with different models. On October 29, two of the three went to nvidia/nemotron-3.5-content-safety:free, a 4B guardrail model built to classify content rather than follow chat instructions. On November 3, two went to Nemotron 3 Nano Omni Reasoning and one to Nemotron 3 Ultra.
The response's model field tells you which model you got. For a quick demo the router is fine. In a workflow that parses the output, a random switch to a different model, or to a safety classifier, breaks things in ways that are hard to debug.
What does the "only available on agentic harnesses" 403 mean?
Both Thinking Machines Inkling models return 403 to direct API calls: "only available on agentic harnesses. Try plugging it into a coding agent or productivity app listed on https://openrouter.ai/apps". The model is free, but only through the apps OpenRouter lists. Calls from your own code get the 403. The endpoints API still lists both, and Inkling Small shows 99.9% uptime over the last day, so a catalog-only check would count it as working. Both also carry an expiration date of November 4, 2026.
How do you use free models without your app breaking?
Treat a :free ID as a temporary promotion with no notice period, then build around that.
- Put a paid fallback in every request. OpenRouter's
modelsparameter takes an ordered list, and by default any error, rate limiting included, moves to the next model. You pay only for the model that served the request, at that model's rate."models": ["nvidia/nemotron-3-ultra-550b-a55b:free", "openai/gpt-oss-120b"]keeps you on the free model until it fails. - Read
expiration_datefrom the catalog./api/v1/modelsreturns it per model. On October 29 it showed 2026-10-31 for both Laguna 2.1 free models, and both were gone by November 3. Today it shows 2026-11-04 for both Inkling models and 2026-12-31 for Dots3-Note Preview. A weekly job that alerts on dates in the next 14 days costs nothing. - Probe, don't trust the listing. Three listed free models returned 429 on every call, two more failed with provider errors, and two only answer inside approved apps. Recursive Flint was one of the most reliable models on October 29 and failed every call five days later. Our script takes a few minutes, and the November 3 probe run used 22 of our daily free requests.
- Log the
modelfield. It records which model actually answered, and that matters most when you use the router or a fallback chain.
This is the same design problem as surviving a paid model being pulled, just on a shorter clock. Our AI model failover architecture guide covers health checks, circuit breakers and eval sets for the fallback models. If you'd rather have this wired into your product by people who run it in production, that is what our AI integration services team does: model routing, fallbacks and cost controls around the APIs you already use.
Re-run the check yourself
The script is plain Python with no dependencies: check.py. The raw results are in the same folder: snapshot-2026-11-03.json has every probe's HTTP status, latency, serving provider and error text for this post, and snapshot-2026-10-29.json has the earlier run.
# catalog + endpoints only, no key needed
python3 check.py

# also send 3 test calls per free model (free, but counts against your daily :free quota)
OPENROUTER_API_KEY=sk-or-... python3 check.py --probe
It writes a dated JSON snapshot and prints both tables in this post. Edit the WATCHLIST at the top to track the IDs your own code depends on.
For free options outside OpenRouter, our free AI models directory lists free API tiers by provider, and free AI models for coding compares the ones that suit coding agents. The directory pages for OpenRouter models that are no longer free now say so and give the paid ID. If you were using Tencent Hy3 through its launch promotion, the Hy3 free API post covers the model itself; tencent/hy3:free now redirects you to the paid slug.
FAQ
Does OpenRouter still have free models?
Yes. On November 3, 2026, the models API lists 14 :free IDs plus the openrouter/free router. Six of the 14 answered all three of our test calls. Three returned 429 every time, two failed with provider errors, and two only work inside approved agent apps.
Is gpt-oss-120b free on OpenRouter?
No. openai/gpt-oss-120b:free returns a 404 saying the model is unavailable for free and pointing to openai/gpt-oss-120b. On November 3 the paid ID had 27 endpoints, and the lowest input price was $0.03 per million tokens ($0.15 output).
Is Qwen3 Coder still free on OpenRouter?
No. qwen/qwen3-coder:free returns a 404 that points to the paid qwen/qwen3-coder. On November 3 that ID had 2 endpoints, from $0.30 per million input tokens and $1.00 per million output tokens.
How many free requests per day does OpenRouter allow?
50 requests per day if you have bought less than 10 credits in total, and 1,000 per day if you have bought 10 or more. Both tiers are capped at 20 requests per minute. Your key's live counter is in free_model_daily_requests on GET /api/v1/key.
Why does my OpenRouter free model return 429?
A 429 comes from one of two places. Either you hit OpenRouter's own free cap (20 a minute, or your daily limit), or the single provider serving that free model is out of capacity for free traffic. OpenRouter's limits page says the second kind carries the provider's original code in error.metadata.provider_code. Every :free model in our check had exactly one provider. Gemma 4 31B and 26B returned 429 on all six calls, even while their endpoints showed 100% one-day uptime. Add a paid fallback with the models parameter so a 429 moves the request instead of failing it.
What should I replace a dead :free model with?
Use the paid ID the 404 message gives you if the price fits, or move to a listed free model with a paid fallback behind it. For the same model family, the paid slug is usually the safer choice: openai/gpt-oss-120b costs $0.03 per million input tokens and had 27 providers on November 3. If you need help choosing and wiring the routing, our custom workflow automation team builds this into production workflows.
How often does the OpenRouter free model list change?
Often enough that you should check it on a schedule. Between our runs on October 29 and November 3, two free models expired, three stopped answering and two recovered. Three of today's 14 IDs carry an expiration date. Re-run our script weekly, or watch the expiration_date field in /api/v1/models.
Sources: OpenRouter models API and per-model endpoints API (/api/v1/models/<id>/endpoints), pulled 2026-11-03 09:19 UTC (earlier run 2026-10-29 01:01 UTC); OpenRouter API rate limits, read 2026-11-03; OpenRouter model fallbacks, read 2026-11-03; our own probe runs and raw data: /benchmarks/openrouter-free-models/.
Book a Free Strategy Call
Building this in production?
Walid runs a 30-min call to map your AI engineering team. Free, no slides.
Free weekly brief
Steal our production automations
The exact n8n flows, Claude Code setups, and prompts we ship for clients, broken down step by step. No spam, unsubscribe anytime.
Ex-IBM AI engineer and enterprise architect. Adel owns the technical architecture behind every automation and AI agent system AY Automate ships.